Build a semantic layer for agentic AI with EDB Postgres AI and Amazon Bedrock AgentCore
Build a semantic layer for agentic AI with EDB Postgres AI and Amazon Bedrock AgentCore
The AWS Machine Learning Blog shows how to build a semantic layer for agentic AI with EDB Postgres AI and Amazon Bedrock AgentCore: the AIDB extension embeds a semantic knowledge base (SemKB) into operational Postgres databases, governs it through COMMENT statements, foreign key join graphs, GRANT and row-level security, and registers it with the AgentCore Gateway via a built-in MCP endpoint.
In this post, we show how to build a semantic layer for agentic AI using EDB Postgres AI. We run a Strands Agents agent on Amazon Bedrock AgentCore that queries the layer to answer customer 360 (C360) questions. Earlier posts in this series built the same C360 pattern with Stardog’s knowledge graph, Denodo’s data virtualization platform, AtScale’s dimensional model, and Strategy Mosaic’s linked models.
EDB Postgres AI puts the semantic layer inside the operational Postgres database as an AIDB extension. Business meaning lives next to the data in standard Postgres COMMENT statements, the join graph comes from Postgres foreign keys, and governance uses Postgres GRANT and row-level security through the Model Context Protocol (MCP) endpoint that ships with AIDB.
By the end of this post you will know:
- How to build an AIDB semantic knowledge base (SemKB) over a Postgres schema, how
COMMENT ONstatements andaidb.create_semantic_aliasbehave as the authoring surface, and how foreign keys crawl into join paths. - How to expose the AIDB tool catalog to an external agent through the built-in EDB MCP endpoint, fronted by an Application Load Balancer (ALB) and registered as an MCP target on AgentCore Gateway, a capability of Amazon Bedrock AgentCore.
- How Postgres roles, column-level
GRANTstatements, and row-level security produce different results for different callers. The prompt, tool catalog, and agent code stay the same. - How AIDB captures OpenTelemetry traces for every SQL execution as rows in the
aidb_otelschema, queryable with ordinary SQL.
Three layers an agent needs
An agent that answers business questions from live data needs three layers: a model that plans and writes queries, a meaning layer that tells the agent what the data represents, and a runtime that hosts the agent and controls identity and access. The Stardog post in this series introduced this framing. The model layer in this post is Anthropic Claude on Amazon Bedrock, the same as prior posts (model availability varies by AWS Region). The runtime layer is AgentCore runtime, a capability of Amazon Bedrock AgentCore. AgentCore Gateway handles inbound authorization, and AgentCore Identity, a capability of Amazon Bedrock AgentCore, holds outbound credentials for the tool targets, same as prior posts. EDB Postgres AI hosts agents and tools inside the database itself and acts as the connection point for external agents through its MCP endpoint.
The meaning layer is where this post diverges from the others. Here it is a SemKB that lives inside the operational Postgres database. The schema and the business definitions are indexed together. Postgres GRANT, row-level security, and column-level grants enforce access, not an advisory system prompt. The sections that follow cover how AIDB builds the layer, how AgentCore exposes it, and how two Postgres roles asking the same question get different answers.
Example use case: C360 on EDB Postgres AI
The dataset is the Stardog C360 Knowledge Kit, loaded into a single EDB Postgres AI instance in a dedicated c360 schema. The data model has four tables and one derived view.
| Object | Key columns |
customers |
cid, first_name, last_name, full_name, email, ssn, phone, picture, location (FK to locations.id) |
locations |
id, city, state, zip |
products |
id, name, brand, dept, price |
purchases |
id, cid (FK to customers.cid), pid (FK to products.id), date, quantity, price |
big_spender (view) |
cid, full_name, state, large_orders, largest_order |
The physical schema is a plain Postgres join graph: a customer in the customers table lives at a location, places purchases, and each purchase references a product. The semantic work rests on three business ideas that column names don’t reveal.
State isn’t on the customer row. It lives in locations, reached through the customers.location foreign key, and a comment on that column tells SemKB where to find it.
purchases.price records the order total. An agent that reads it as a unit price and multiplies by quantity returns $502,529 for the top customer instead of $27,991.66.
Big spender is a term the business owns. Captured as a view with a COMMENT ON VIEW statement, its definition stays in one place that every agent, dashboard, and query reads from.
The questions we run through the agent end to end:
- Who are our top 10 customers by total spend, and what state is each in?
- How many big spenders do we have in each state?
- Can you list 10 customers and the state each lives in?
- Which 10 products have sold the most units?
- Can you list five customers with their Social Security numbers? (used in the governance rerun).
Reference architecture
The following diagram shows the request path from the analyst through Amazon Bedrock AgentCore to the semantic layer inside EDB Postgres AI. The analyst authenticates with Amazon Cognito and calls AgentCore Gateway with the issued JSON Web Token (JWT) as a Bearer token. Gateway routes to AgentCore runtime, which plans with Claude on Amazon Bedrock. The agent calls MCP tools through Gateway, which forwards to an Application Load Balancer in the EDB Postgres AI virtual private cloud (VPC) and on to the edb-endpoints MCP server inside AIDB. AIDB serves the SemKB, semantic aliases, and read-only PostgreSQL tables. AgentCore traces go to Amazon CloudWatch, and AIDB captures OpenTelemetry traces as rows in the aidb_otel schema inside Postgres.
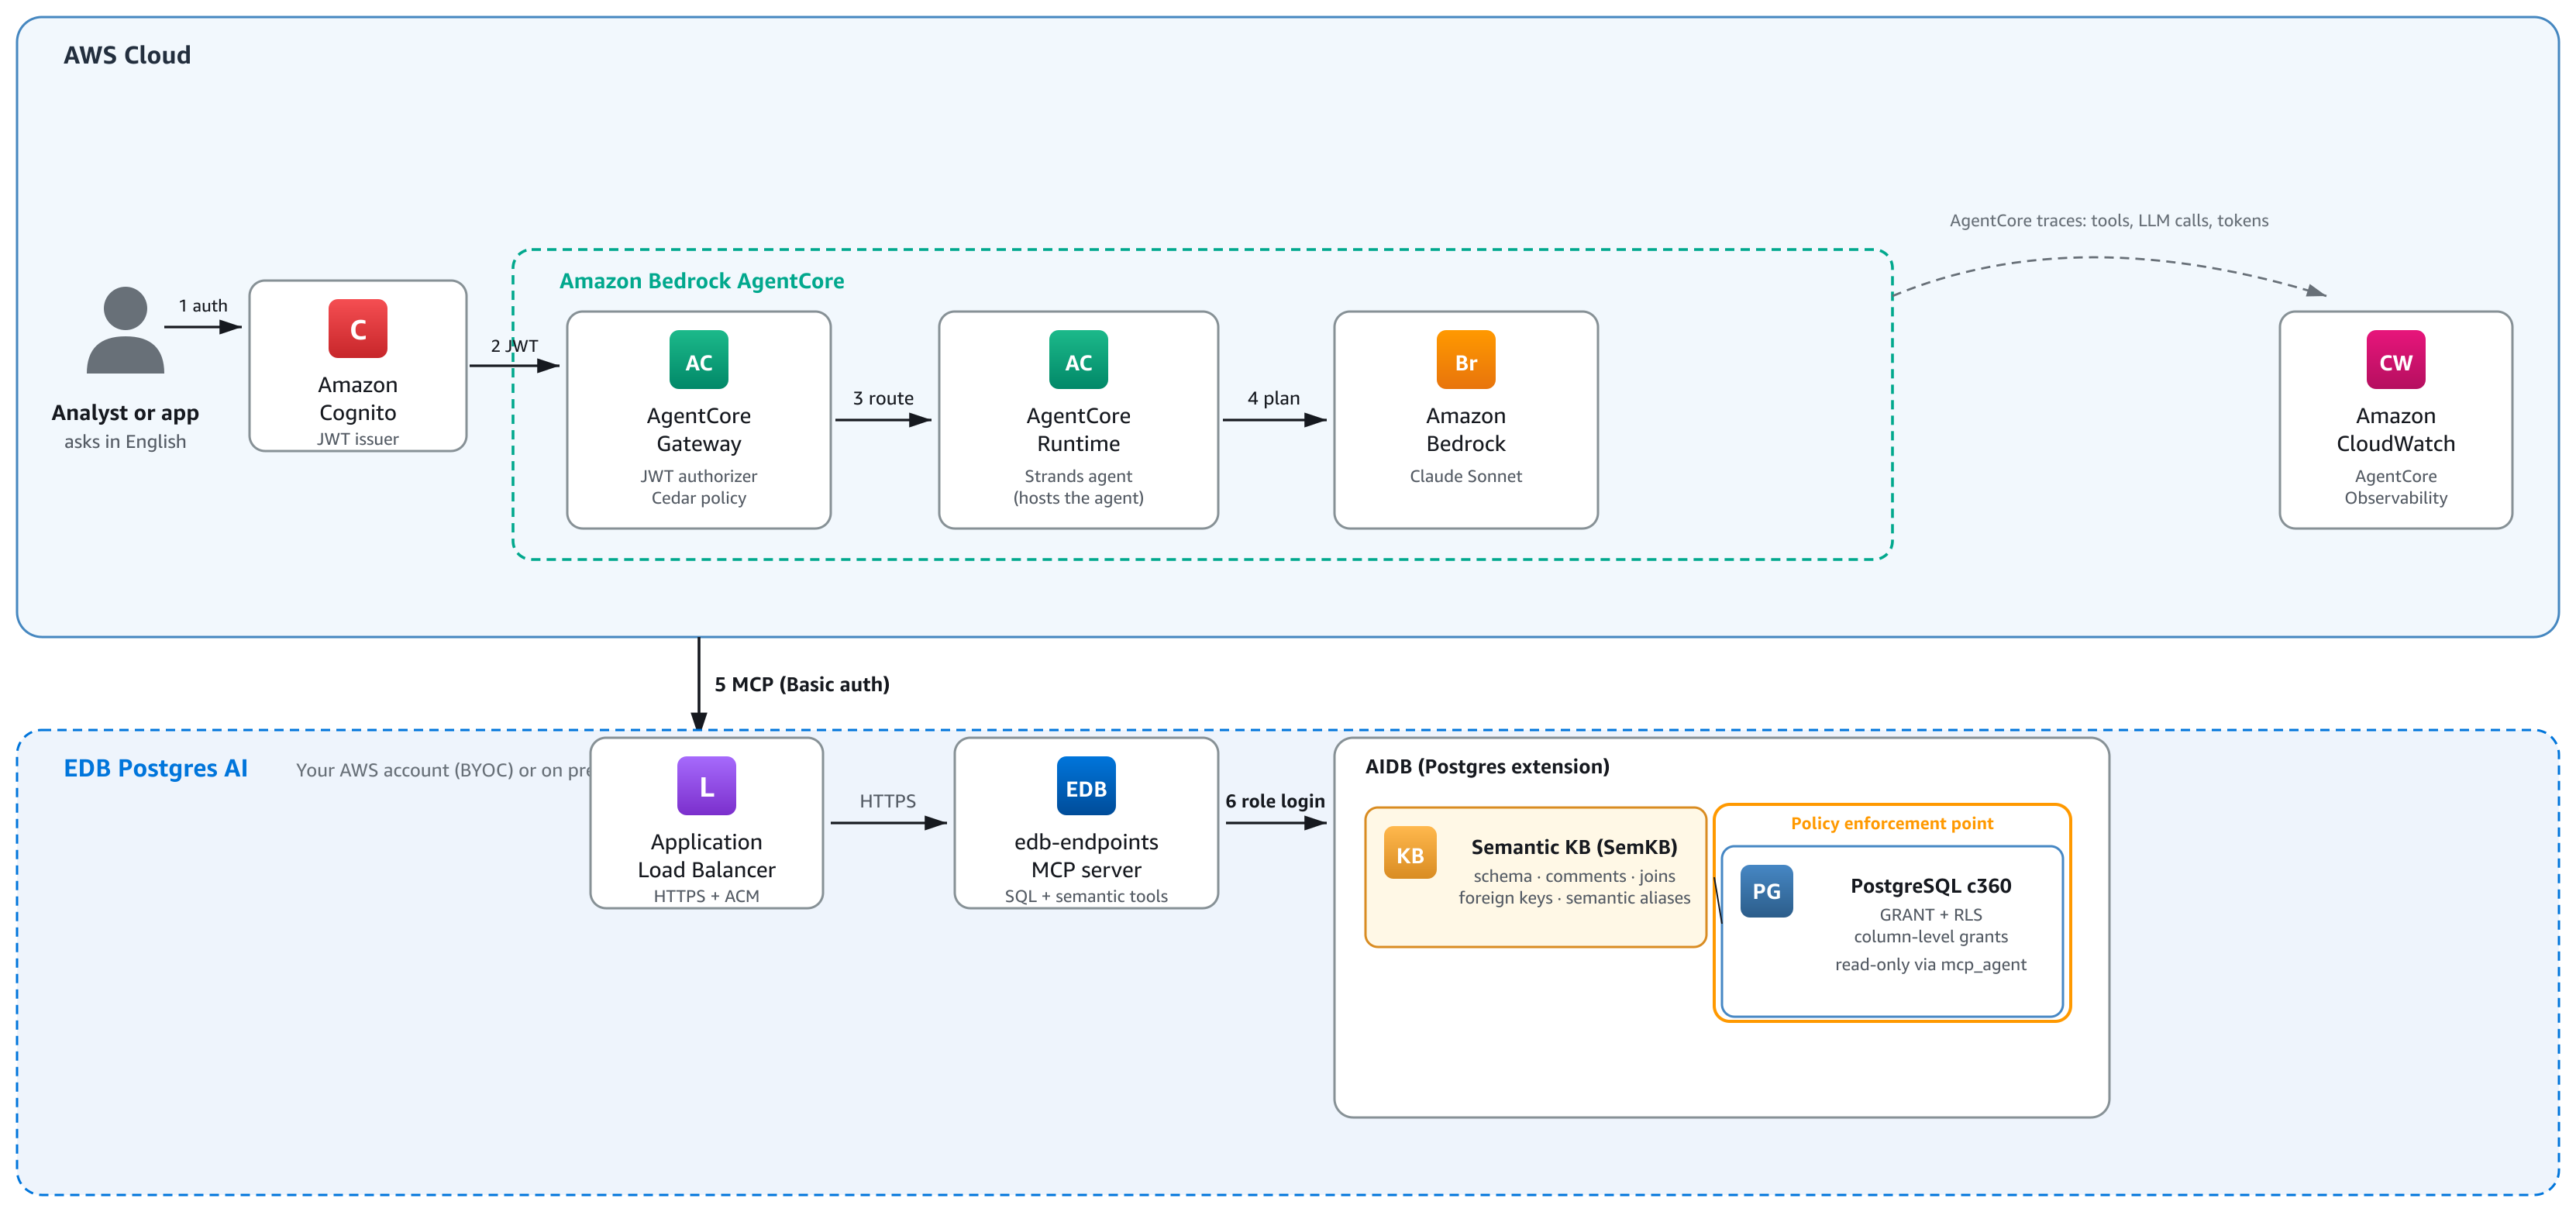
Figure 1: Reference architecture for EDB Postgres AI and Amazon Bedrock AgentCore
Two flows cross the boundary between AgentCore and EDB Postgres AI.
Inbound: A client calls AgentCore Gateway with a bearer token issued by an Amazon Cognito user pool. The Gateway inbound JWT authorizer validates the token against the Cognito discovery URL. Gateway then evaluates its Cedar policy against the token’s claims to decide which tools this agent, acting for this user, can invoke. It then routes the call to AgentCore runtime. The agent invokes Claude on Amazon Bedrock for planning and answer composition.
Outbound to the semantic layer: The agent’s tool call is an MCP request. AgentCore Gateway supports MCP server targets directly. AIDB’s edb-endpoints HTTP server speaks streamable HTTP MCP with HTTP Basic authentication, which lets Gateway treat it as an MCP server target with no translation layer. An Application Load Balancer with an HTTPS listener and an AWS Certificate Manager (ACM) certificate fronts edb-endpoints on an Amazon Elastic Compute Cloud (Amazon EC2) instance. The ALB URL is registered as the Gateway target. The AgentCore Identity credential provider holds the Postgres role credential and injects it as Basic auth on every outbound request. The agent code doesn’t see the Postgres credential.
Observability: AgentCore emits traces for tool calls, large language model (LLM) calls, and token usage to CloudWatch Transaction Search. AIDB captures OpenTelemetry traces for SQL execution as rows in the aidb_otel schema inside Postgres, queryable with ordinary SQL after the database is configured to write them (see enabling telemetry on the source database).
No AWS Lambda is required in this architecture. AIDB already speaks MCP, so Gateway talks to it as an MCP server target directly through the ALB. The Denodo post in this series uses the same ALB pattern in front of its MCP server, and the architecture here is unchanged other than the vendor.
Build the semantic layer
These steps assume AIDB is installed and enabled on the EDB Postgres AI instance and the Stardog C360 kit’s four CSVs are loaded into a dedicated c360 schema with the primary and foreign keys shown earlier. Because this layer lives in the same database as the data, there is no second system to deploy and no catalog to synchronize. The semantic layer is defined in SQL, inside the same database as the application that writes the rows.
An AIDB semantic knowledge base indexes Postgres schema, not data. It embeds the definition of every table, view, and column (with the COMMENT ON text alongside) into a vector store that an agent can search in natural language. Three authoring tasks help the agent find the right table and column by meaning: writing COMMENT ON statements, defining business terms as views with their own comments, and registering recurring questions as semantic aliases. Comments are the simplest of the three authoring tasks and improve text-to-SQL accuracy the most for both users and agents.
COMMENT ON COLUMN c360.purchases.price IS
  'Total amount the customer paid for the entire order, in US dollars. Not the unit price.';
COMMENT ON COLUMN c360.purchases.cid IS
  'Customer who placed the order. Joins to customers.cid.';
COMMENT ON COLUMN c360.customers.location IS
  'Home address of the customer. Joins to locations.id. State is in locations.state.';
COMMENT ON COLUMN c360.customers.ssn IS
  'US Social Security number. Sensitive, column-level grant required.';

CREATE VIEW c360.big_spender AS
  SELECT c.cid, c.full_name, l.state,
         count(*)      AS large_orders,
         max(pu.price) AS largest_order
    FROM c360.purchases pu
    JOIN c360.customers c ON c.cid = pu.cid
    JOIN c360.locations l ON l.id  = c.location
   WHERE pu.price > 250
   GROUP BY c.cid, c.full_name, l.state;

COMMENT ON VIEW c360.big_spender IS
  'Big spenders. A big spender is a customer with at least one order over 250 US dollars. '
  'Use this view for any question about big spenders.';
The view holds the business definition in one place, so no agent or dashboard has to redefine big spender. The time you spend on comments up front pays off on every query the agent runs afterward.
Create the semantic knowledge base
Create the SemKB over the c360 schema. The call registers the name, the embedding model, the target schemas, and the auto-processing mode.
SELECT aidb.create_semantic_kb(
    name            => 'c360_kb',
    model           => 'bge-small-en-v1.5-f16',
    schemas         => ARRAY['c360'],
    auto_processing => 'Live'
);
The embedding model is a local llama.cpp model (llamacpp_embeddings) that ships with the AIDB Amazon Machine Image (AMI). SemKB uses one embedding model per KB, so every entry sits in the same vector space. The AIDB AMI ships with a default SemKB named semkb over public, so creating c360_kb leaves two SemKBs on the instance. When more than one SemKB exists, every aidb.semantic_kb_search call must pass kb_name explicitly. To swap the local model for a remote embedding model, such as Amazon Titan Text Embeddings on Amazon Bedrock, register the remote model with aidb.create_model. Pass its name as the SemKB’s model parameter. The auto_processing parameter accepts Disabled, Live, or Background. Live reacts to schema changes through Postgres event triggers. Background processes them asynchronously from a worker. Disabled waits for an explicit aidb.refresh_semantic_kb(). SemKB also crawls foreign keys into relationships at the same time. The purchases.cid foreign key becomes a join path the agent can discover by meaning, not by column name.
Capture recurring questions as semantic aliases
A semantic alias is a named, parameterized read-only SELECT with a natural-language description that SemKB indexes alongside the schema metadata. The agent finds it by meaning, calls it with parameters, and returns a governed answer.
SELECT aidb.create_semantic_alias(
    name        => 'big_spenders_by_state',
    description => 'Count big spenders grouped by state, ordered from most to fewest.',
    query_text  => $$SELECT state, count(*) AS big_spenders
                     FROM c360.big_spender
                     GROUP BY state
                     ORDER BY big_spenders DESC, state$$,
    params      => '[]'
);
Aliases are AIDB’s reusable text-to-SQL building block. They sit next to tables and views in the SemKB index and show up to an agent as a tool. For a full text-to-SQL walkthrough, see the EDB documentation.
Govern access
Governance in this architecture runs through Postgres primitives all the way down. The AIDB MCP endpoint has no permission system of its own: “Postgres grants decide what each agent can run” (MCP endpoint reference). Each MCP request authenticates with a Postgres username and password over its own connection, so current_user inside every tool call is the agent’s role, visible in pg_stat_activity like other connections.
The following diagram traces how identity flows from the end user through AgentCore to the Postgres role that evaluates the SQL, and how the resulting trace is captured for audit. The chain runs in four phases: inbound trust at the Gateway, outbound credential from AgentCore Identity, enforcement in Postgres through GRANT and row-level security, and audit through OpenTelemetry traces in the aidb_otel schema.
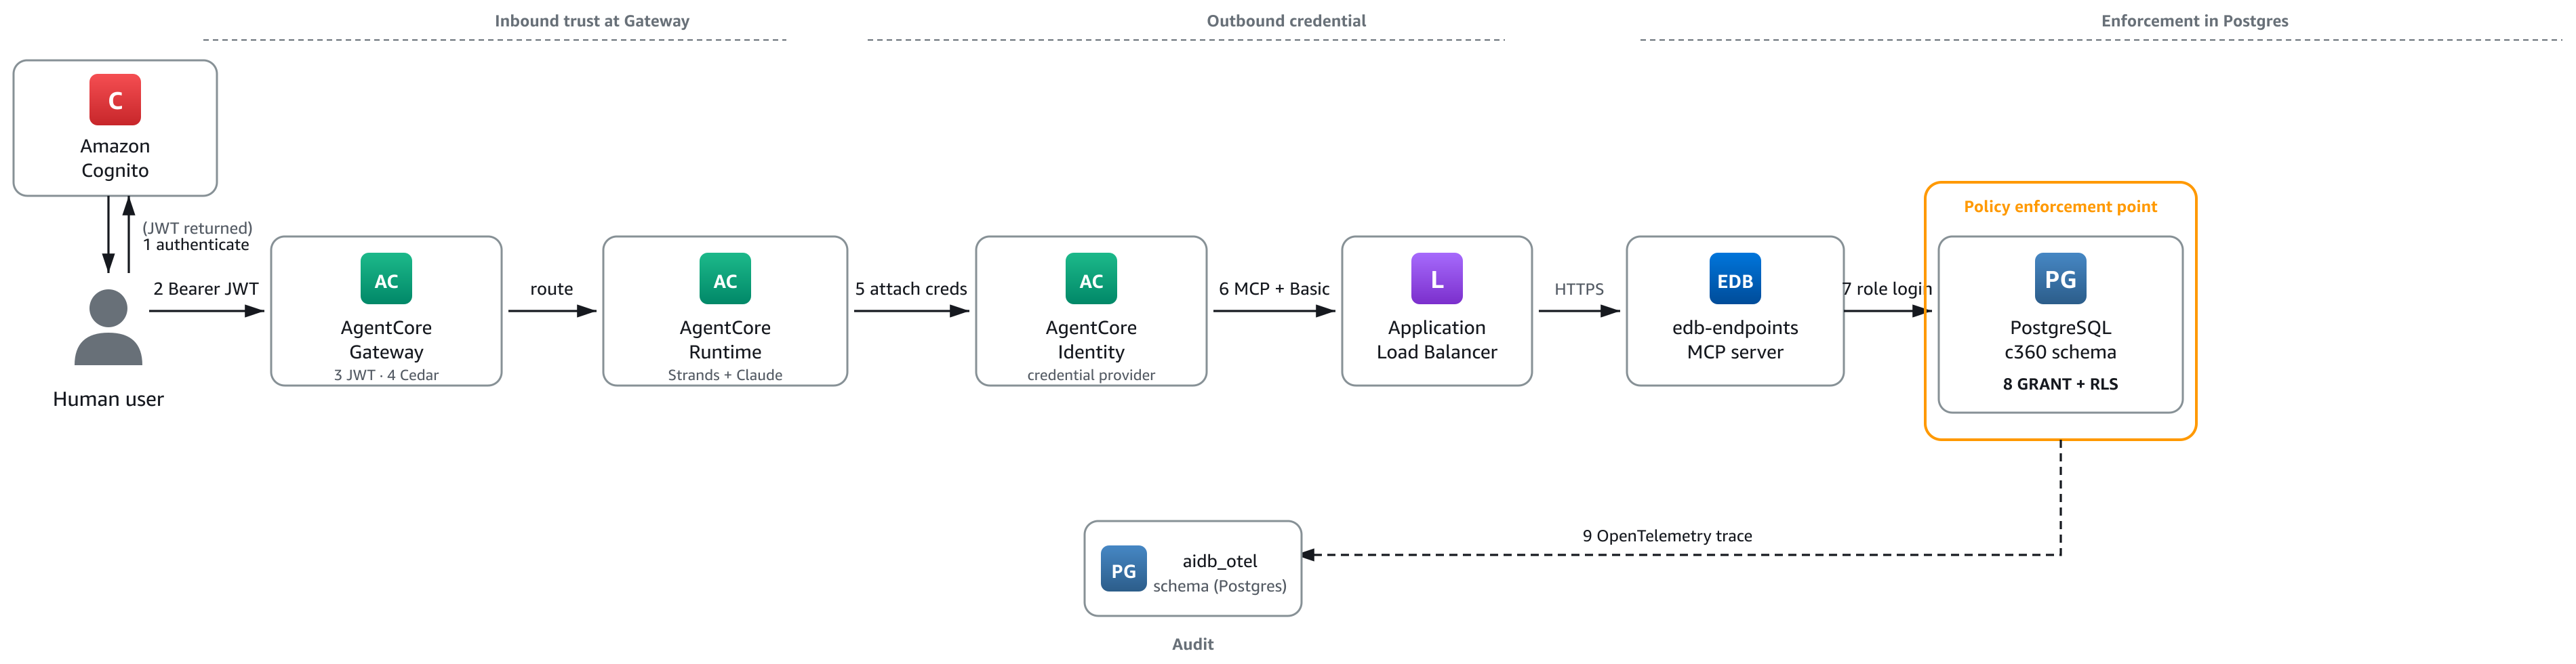
Figure 2: Identity propagation chain from the end user to the Postgres role that evaluates the SQL
Inbound trust at Gateway: 1. The end user authenticates with Amazon Cognito and receives a JWT bearer token. 2. The client calls AgentCore Gateway with the token in the Authorization header. 3. The Gateway JWT authorizer validates the token against the Cognito user pool’s discovery URL. 4. Gateway evaluates its Cedar policy against the token’s claims to decide which tool this agent can call.
Outbound credential to AIDB: 5. Gateway resolves the outbound credential for the MCP target from the AgentCore Identity credential provider. For AIDB, this is a Postgres username and password used as HTTP Basic auth. 6. Gateway forwards the MCP streamable-HTTP request to the ALB, which forwards it to edb-endpoints.
Enforcement in Postgres: 7. edb-endpoints opens a Postgres connection using the username and password from the Basic auth header. Postgres authenticates the login role per pg_hba.conf, and current_user inside the tool call is that role. 8. Column-level GRANT statements and row-level security policies on c360 tables enforce what rows and columns the tool call returns. A denial surfaces as a Postgres permission-denied error on the restricted table or column, which the MCP endpoint forwards unchanged.
Audit. 9. AIDB captures OpenTelemetry traces for the SQL execution as rows in the aidb_otel schema, available through SQL immediately.
Two Postgres roles, same question, different results
Define two agent login roles that differ only in a column-level GRANT: mcp_agent_full sees every column, mcp_agent_restricted sees every column except customers.ssn.
CREATE ROLE mcp_agent_full       LOGIN PASSWORD '...';
CREATE ROLE mcp_agent_restricted LOGIN PASSWORD '...';

GRANT USAGE ON SCHEMA c360 TO mcp_agent_full, mcp_agent_restricted;

-- Both roles need aidb_users to list MCP tools
GRANT aidb_users TO mcp_agent_full, mcp_agent_restricted;

-- Full role sees every column
GRANT SELECT ON ALL TABLES IN SCHEMA c360 TO mcp_agent_full;

-- Restricted role sees every table and view, with customers.ssn withheld
GRANT SELECT ON c360.locations, c360.products, c360.purchases, c360.big_spender
  TO mcp_agent_restricted;
GRANT SELECT (cid, first_name, last_name, email, phone, picture, location, full_name)
  ON c360.customers TO mcp_agent_restricted;
Both login roles need password-auth entries in pg_hba.conf for the local edb-endpoints connection path, as covered in configuring your agent role. Running the same question through both roles produces different results. The agent calling under mcp_agent_restricted can’t project the ssn column: the moment it tries, Postgres returns permission denied for column ssn and the MCP endpoint forwards that error unchanged. The agent then responds that it can’t read SSNs. The prompt, the tool catalog, the SemKB, and the agent code are identical between the two roles. The only difference is the credential AgentCore Identity injects on the outbound Basic auth header.
Row-level filtering follows the same pattern. Enable row-level security (RLS) on a target table and attach per-role USING policies. The AIDB MCP endpoint sees the same rows the role would see in a direct psql connection.
A note on AIDB purposes. AIDB also ships purposes, a policy abstraction that confines in-database agents (those created with aidb.create_agent and invoked with aidb.agent_converse) to a named Postgres role. Purposes apply to the in-database agent path. The external AgentCore path this post uses governs through Postgres roles directly at the MCP endpoint, as described earlier. For audit of external MCP agents, see EDB Agent Governance, which reads the same aidb_otel spans and visualizes agent sessions and policy decisions.
Responsible AI considerations. The governance surface shown so far controls what the agent can execute at the database layer. Pair it with Amazon Bedrock Guardrails on the model side to shape what the agent is allowed to generate: content filters for sensitive topics, denied-topic lists, and PII redaction. The two layers complement each other. Postgres GRANT stops the agent from reading SSNs at the data layer. Guardrails help prevent PII patterns from leaking through other paths in the model response. For agents answering business questions over customer data, both are production controls.
Expose the layer and run the agent
Enabling the AIDB MCP endpoint takes two Postgres parameters plus a restart. Set edb.endpoints_mcp_enabled = on in postgresql.conf, add aidb to shared_preload_libraries, and restart (enabling the endpoint). To reach the endpoint from outside the EC2 instance, set edb.endpoints_mcp_host to a non-loopback address such as 0.0.0.0. Choose a port with edb.endpoints_mcp_port (default is 8765). Supply the Transport Layer Security (TLS) pair with edb.endpoints_mcp_tls_cert and edb.endpoints_mcp_tls_key, which the endpoint requires for non-loopback binds (configuring the endpoint).
An Application Load Balancer with an HTTPS listener and an ACM certificate exposes edb-endpoints to AgentCore Gateway. The ALB target group uses HTTPS to the EC2 instance on port 8765 and doesn’t validate the backend certificate chain, so a self-signed certificate on edb-endpoints is sufficient for development and testing. For production, use an internal ALB with AgentCore Gateway VPC egress to keep connectivity between Gateway and the ALB private.
Create an AgentCore Gateway with a Cognito authorizer, register the ALB URL as an MCP server target, and store the two Postgres credentials in the AgentCore Identity credential provider (credential provider reference).
The agent is a short Python script. It uses Strands Agents to wire a BedrockModel pointing at the latest Claude Sonnet to an MCPClient. The MCPClient connects to the Gateway URL over the streamable HTTP MCP transport with the Cognito access token as a Bearer header. The system prompt instructs the agent to call semantic_kb_search first for schema context, passing kb_name => 'c360_kb', then execute_sql to run the generated query. The AgentCore runtime starter toolkit with Strands has a worked example of hosting an agent of this shape in production.
We recommend turning on Amazon Bedrock prompt caching for the agent’s system prompt. The same instruction and the same tool list are reused on every call, which is what prompt caching is for.
Sample queries and verification
Four questions through the agent plus one governance rerun, all against the C360 data loaded earlier.
Query 1: Who are our top 10 customers by total spend, and what state is each in?
Without the comment on purchases.price, an agent configured with only a SQL execution tool reads price as a unit price and multiplies by quantity. The top row comes back as roughly $502,529 for Carolyn Inworth, which is wrong. One column comment, indexed by SemKB, is the entire difference between that answer and the right one:
     full_name     |     state      |   spent
-------------------+----------------+----------
 Carolyn Inworth   | Wisconsin      | 27991.66
 Marlane Shadwick  | Florida        | 22677.05
 Isaac Popping     | Pennsylvania   | 20085.96
 Bria McKellar     | Texas          | 19588.80
 Mike Laydel       | Louisiana      | 18651.28
 Fayette Mor       | Arizona        | 17993.69
 Reynard Perigoe   | Florida        | 17019.55
 Humfrey Fores     | California     | 16811.16
 Patrice Jakeway   | California     | 16656.72
 Mord Pettus       | North Carolina | 16604.37
Same model, same prompt, same tool catalog. The semantic knowledge base changes the answer.
Query 2: How many big spenders do we have in each state?
The agent finds the big_spender view through semantic_kb_search because its COMMENT ON VIEW matches the natural-language question. The business definition sits in exactly one place:
        state         | big_spenders
----------------------+--------------
 Florida              |           46
 Texas                |           46
 California           |           42
 District of Columbia |           24
 New York             |           23
 ...
If the business later redefines a big spender as a customer with cumulative spend over $5,000, the change is one CREATE OR REPLACE VIEW statement. Every agent sees the new definition the next time SemKB refreshes.
Query 3: List 10 customers and the state each lives in
The state is in locations, not customers. The join path is encoded in the customers.location foreign key and in the column comment, both indexed by SemKB. The agent emits:
SELECT c.cid, c.full_name, l.state
  FROM c360.customers c
  JOIN c360.locations l ON l.id = c.location
 ORDER BY c.cid
 LIMIT 10;
cid | full_name | state
-----+-----------------------+----------------
1 | Jolynn Bithany | Texas
2 | Mord Pettus | North Carolina
3 | Lavinie Stannislawski | Florida
4 | Kimball Evenett | Alabama
5 | Linnie Meatcher | California
6 | Lorens Stoneley | Washington
7 | Juliane Gerhartz | California
8 | Jacob O'Lyhane | Utah
9 | Terrel Seller | Missouri
10 | Jannel Gawthrope | CaliforniaQuery 4: Which 10 products have sold the most units?
A plain aggregation that runs inside Postgres next to the data:
SELECT p.name, sum(pu.quantity) AS units
  FROM c360.purchases pu
  JOIN c360.products  p  ON p.id = pu.pid
 GROUP BY p.id, p.name
 ORDER BY units DESC, p.id
 LIMIT 10;
name | units
--------------------+-------
Markers | 160
Cleaning Wipes | 155
Playset (Girl's) | 146
Queen Sheet Set | 138
Mechanical Pencils | 137
Shot Glasses | 133
Parchment Paper | 127
American Cheese | 127
Pop Music | 127
Varnish | 125The same prompt runs twice. Under mcp_agent_full, the agent returns five customer rows with their ssn values populated. Under mcp_agent_restricted, the agent’s tool call fails with the Postgres error permission denied for column ssn, and the agent responds with a short message that SSNs are not accessible to this caller. The failure is enforced by the column-level GRANT, not by the prompt or the model. AIDB captures the OpenTelemetry trace for the SQL execution in aidb_otel, so a reviewer can query the trace row to confirm the governance decision later.
Extending across data sources
For analytical workloads that outgrow the operational database, EDB Postgres Analytics Accelerator (PGAA) lets Postgres read Apache Iceberg, Delta Lake, and Parquet tables in object storage through an Iceberg REST catalog. The EDB Postgres AI analytics overview covers the end-to-end setup. PGAA tables appear in Postgres as ordinary tables, so the same SemKB description keeps working against the analytical copy and the agent’s tool catalog doesn’t change.
For federation to external relational sources, Postgres foreign data wrappers make an external table reachable as if it were local. The semantic layer is unchanged in either case because business definitions, column comments, and semantic aliases live in Postgres.
Deployment
Two shapes work for this architecture.
Self-managed on Amazon EC2. Use the EDB Postgres AI Agent Factory AMI from the AWS Marketplace. The customer owns the VPC, the subnet, the version cadence, and the EDB Postgres AI software upgrades. The ALB and the AgentCore Gateway target configuration are unchanged from the preceding architecture.
EDB-managed on Amazon EC2. EDB Managed Database is a service where EDB experts handle database administration on the customer’s behalf. The AgentCore side is unchanged.
Conclusion
Reliable agentic analytics needs three things working together: a foundation model that can plan and generate queries, a semantic layer that provides a governed business view of the data, and an agent runtime that hosts the agent and manages identity. Amazon Bedrock supplies the model, Amazon Bedrock AgentCore supplies the runtime, and EDB Postgres AI supplies a semantic layer that lives inside the operational Postgres database. Business meaning, join paths, and governance come from Postgres primitives already present in the schema. The AWS side is the same as the rest of this series: AgentCore Gateway, Runtime, Identity, Bedrock, and CloudWatch.
The data, the business definitions, and the access rules all live in one Postgres schema, so there is no separate catalog to keep in sync. Audit lives in the same database: aidb_otel holds a span per tool call, next to the data it ran against.
Where to start
To apply this architecture to your own data, work through these steps:
- Pick one Postgres database your agents need to query live. Narrower is better.
- Create a dedicated schema for the agent’s data, with
GRANT USAGEscoped to a service role. - Write
COMMENT ONstatements on columns and views that use business language. Capture business terms as views with aCOMMENT ON VIEWstatement. - Create a SemKB over the schema with
aidb.create_semantic_kbandauto_processing => 'Live'(orBackgroundunder high write volume). - Register recurring questions as semantic aliases.
- Enable the AIDB MCP endpoint, front it with an ALB with HTTPS and an ACM certificate, and register the ALB URL as an AgentCore Gateway MCP server target.
- Run three real questions through the agent, then rerun one under a role with reduced grants to confirm the enforcement surface works end to end.
About the authors
Source: AWS Machine Learning Blog · aws.amazon.com